

Python使用pytesseract进行OCR识别的环境配置与实战

本文详解Python中使用pytesseract进行OCR识别的完整流程。重点解决常见报错TesseractNotFoundError,通过Homebrew安装Tesseract引擎及依赖库,并提供从安装依赖到调用API识别图片文字的具体代码示例与验证步骤。
Python实现OCR识别:pytesseract
在Python开发中,常使用pytesseract库来执行OCR(光学字符识别)任务,即从图片中提取文字。虽然核心调用代码仅有一行,但在实际部署和运行环境中,配置环节往往容易遇到障碍。
from PIL import Image
import pytesseract

text = pytesseract.image_to_string(Image.open('/Users/alice/Documents/Develop/PythonCode/textinphoto.PNG'))
print(text)
因此,在正式编码前,必须预先安装pillow和pytesseract这两个Python依赖包。
然而,即便安装了上述Python库,运行时仍可能抛出异常:raise TesseractNotFoundError()。具体报错信息为pytesseract.pytesseract.TesseractNotFoundError: tesseract is not installed or it's not in your path,这表明系统未找到Tesseract引擎或路径配置错误。
该错误的根本原因是未安装底层的Tesseract程序。尝试通过pip3 install tesseract安装后,依然提示命令未找到,具体报错截图如下:
alicedembp:~ alice$ pip3 install tesseract
Requirement already satisfied: tesseract in /Library/Frameworks/Python.framework/Versions/3.7/lib/python3.7/site-packages (0.1.3)
alicedembp:~ alice$ tesseract
-bash: tesseract: command not found
经过查阅多方教程,发现需通过Homebrew(brew)进行安装方可解决。具体操作步骤如下:
- 首先安装Homebrew包管理器。
alicedembp:~ alice$ ruby -e "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/master/install)"- 接着使用brew安装leptonica图像库。
alicedembp:~ alice$ brew install leptonica- 随后使用brew安装tesseract引擎。
alicedembp:~ alice$ brew install tesseract- 安装完成后,通过命令行执行tesseract -v检查版本信息。若终端输出版本号及依赖库信息,则表明安装成功。
alicedembp:~ alice$ tesseract
Usage:
  tesseract --help | --help-extra | --version
  tesseract --list-langs
  tesseract imagename outputbase [options...] [configfile...]

OCR options:
  -l LANG[+LANG]        Specify language(s) used for OCR.
NOTE: These options must occur before any configfile.

Single options:
  --help                Show this help message.
  --help-extra          Show extra help for advanced users.
  --version             Show version information.
  --list-langs          List available languages for tesseract engine.

alicedembp:~ alice$ tesseract -v
tesseract 4.0.0
 leptonica-1.78.0
  libgif 5.1.4 : libjpeg 9c : libpng 1.6.36 : libtiff 4.0.10 : zlib 1.2.11 : libwebp 1.0.2 : libopenjp2 2.3.1
 Found AVX2
 Found AVX
 Found SSE
环境配置无误后,即可直接调用代码进行识别,示例代码如下:
alicedembp:~ alice$ tesseract /Users/alice/Documents/Develop/PythonCode/textinphoto.png /Users/alice/Documents/Develop/PythonCode/output.txt代码将打开名为textinphoto.PNG的图片文件,并将识别出的文字内容输出至output.txt文件中。待处理的图片如下所示:

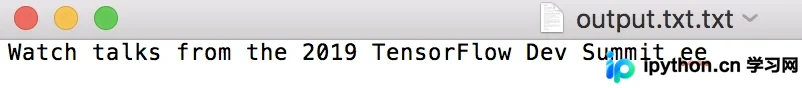
程序运行成功,生成了output.txt文档,其中包含了从图片中成功识别出的文本内容。
到此这篇关于Python实现OCR识别之pytesseract案例详解的文章就介绍到这了,更多相关python OCR识别之pytesseract内容请搜索本站以前的文章或继续浏览下面的相关文章希望大家以后多多支持本站!
免责声明:本文内容仅供参考,不代表本站观点。转载或引用请注明出处。









