

Python多进程高效提取海量文本关键词实战

发布时间:2026-10-13| 4人浏览过
本文介绍利用Python multiprocessing模块的Pool进程池,结合jieba库对海量文本进行高效关键词提取的方法。通过对比单进程与多进程处理581行、7MB语料的耗时,验证了多进程异步处理的性能优势,并指出移除模拟延迟可显著缩短运行时间,为大规模文本分析提供实用参考。
在文本分析场景中,经常需要借助Python代码从文本中提取关键词。面对实际应用中产生的海量数据,若仅采用单进程处理,执行效率往往难以满足需求,因此引入多进程机制成为提升处理速度的有效手段。
Python实现多进程主要依赖multiprocessing模块。当需要处理大量任务时,建议使用进程池(Pool)来管理进程资源。在具体执行过程中,可以通过apply_async函数实现异步任务提交,从而充分利用多核CPU的计算能力。
本次实验使用的语料文件为message.txt,其中包含581行文本数据,总大小约为7MB。处理目标是对每一行文本提取前100个关键词。
具体实现代码如下:
#coding:utf-8
import sys
reload(sys)
sys.setdefaultencoding("utf-8")
from multiprocessing import Pool,Queue,Process
import multiprocessing as mp
import time,random
import os
import codecs
import jieba.analyse
jieba.analyse.set_stop_words("yy_stop_words.txt")
def extract_keyword(input_string):
	#print("Do task by process {proc}".format(proc=os.getpid()))
	tags = jieba.analyse.extract_tags(input_string, topK=100)
	#print("key words:{kw}".format(kw=" ".join(tags)))
	return tags
#def parallel_extract_keyword(input_string,out_file):
def parallel_extract_keyword(input_string):
	#print("Do task by process {proc}".format(proc=os.getpid()))
	tags = jieba.analyse.extract_tags(input_string, topK=100)
	#time.sleep(random.random())
	#print("key words:{kw}".format(kw=" ".join(tags)))
	#o_f = open(out_file,'w')
	#o_f.write(" ".join(tags)+"\n")
	return tags
if __name__ == "__main__":
	data_file = sys.argv[1]
	with codecs.open(data_file) as f:
		lines = f.readlines()
		f.close()

	out_put = data_file.split('.')[0] +"_tags.txt"
	t0 = time.time()
	for line in lines:
		parallel_extract_keyword(line)
		#parallel_extract_keyword(line,out_put)
		#extract_keyword(line)
	print("串行处理花费时间{t}".format(t=time.time()-t0))

	pool = Pool(processes=int(mp.cpu_count()*0.7))
	t1 = time.time()
	#for line in lines:
		#pool.apply_async(parallel_extract_keyword,(line,out_put))
	#保存处理的结果,可以方便输出到文件
	res = pool.map(parallel_extract_keyword,lines)
	#print("Print keywords:")
	#for tag in res:
		#print(" ".join(tag))
	pool.close()
	pool.join()
	print("并行处理花费时间{t}s".format(t=time.time()-t1))
执行命令如下:
python data_process_by_multiprocess.py message.txt
数据文件message.txt中每一行代表一个独立的文档,共计581行,数据总量为7MB。
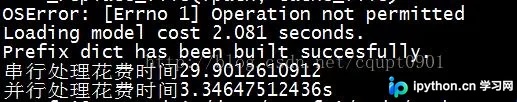
程序运行耗时统计如下:
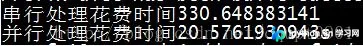
如果在代码中注释掉time.sleep(random.random())这一行,即不通过sleep函数人为挂起进程,可以大幅减少不必要的等待时间,从而显著缩短整体运行耗时。
以上即为Python利用多进程技术提取处理大量文本关键词的完整方法分享,希望能为相关开发者提供有价值的参考,欢迎继续支持本站获取更多技术内容。
免责声明:本文内容仅供参考,不代表本站观点。转载或引用请注明出处。









