

基于Selenium与MongoDB的京东成人用品数据抓取及趋势分析

本文详解如何利用Selenium技术抓取京东平台成人用品的产品信息与评论数据,并存入MongoDB数据库。通过对8934款产品及17万条评论的分析,揭示了销量领先的品牌分布、热门产品特征及购物节对销量的显著影响,为电商数据分析提供实战参考。
项目背景与数据抓取方案
近期深入学习了网络爬虫技术,为了检验学习成果,计划开展一个小项目。在浏览某电商平台时,偶然推荐了一款成人用品(TT)产品,浏览后萌生了抓取该类产品信息并进行数据分析的想法,旨在探究哪些品牌在该品类中销量最佳。
本文采用Selenium工具抓取TT相关数据,并将结果存储至MongoDB数据库中。
TT产品信息抓取技术实现
TT产品信息抓取流程
TT产品列表页面的链接地址为
https://list.jd.com/list.html?cat=9192,9196,1502&page=1&sort=sort_totalsales15_desc&trans=1&JL=6_0_0#J_main
上述链接中包含page参数,用于指定当前页码。通过修改该参数,即可遍历并抓取不同页面的TT产品信息。
利用浏览器开发者工具分析如何提取TT产品的关键信息,如名称、品牌、价格及评论数量等。
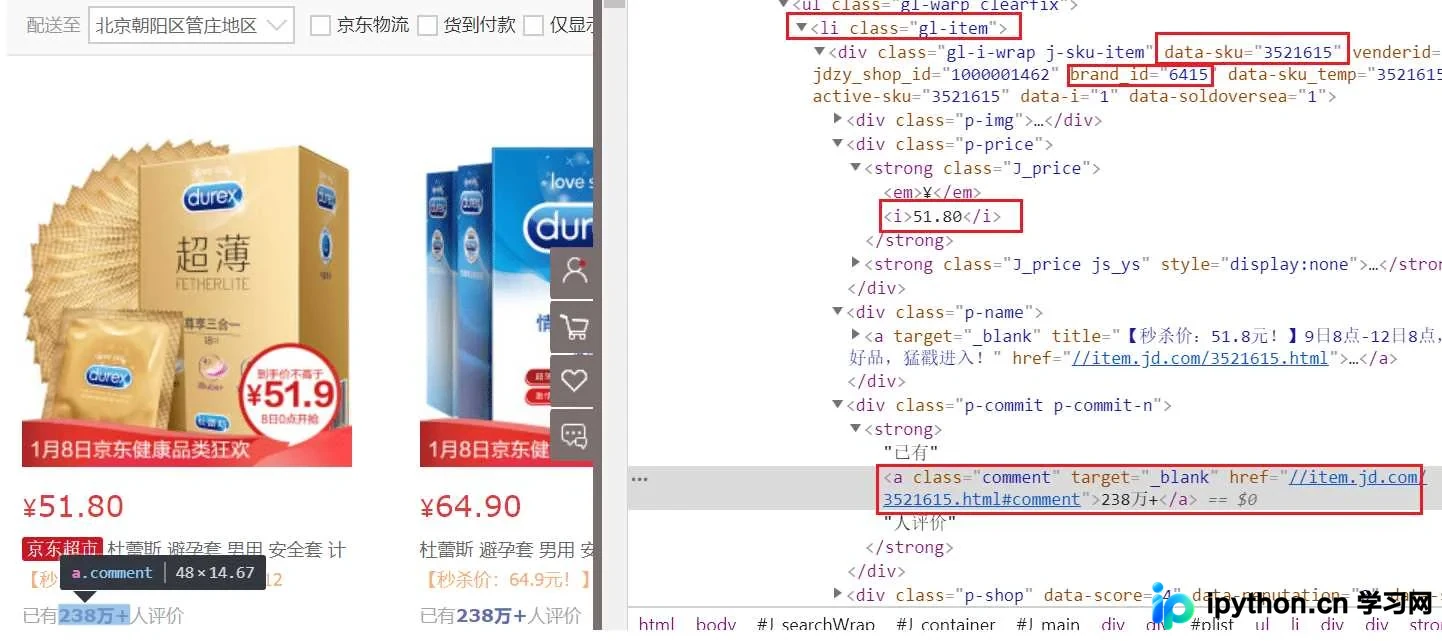
通过上图观察可知,单个TT产品对应的HTML源码是一个class属性为gl-item的li节点<li class='gl-item'>。该li节点中的data-sku属性存储了产品ID,后续抓取评论信息时将用到此ID;brand_id属性则对应品牌ID。class为p-price的div节点包含产品价格信息,而class为p-comment的div节点则对应评论总数信息。
起初尝试使用requests库抓取,但始终无法解析出TT的价格和评论信息。最终改用Selenium成功解决了该问题。若读者有使用requests解决此问题的方案,欢迎分享。
商品评论数据抓取方法
接下来介绍TT产品评论信息的抓取方法。
点击任意TT产品,页面将跳转至商品详情页。点击“商品评论”标签,并勾选“只看当前商品评价”选项(若不勾选,将显示该系列所有产品的评价),即可看到具体商品的评论信息。此时,再次使用开发者工具分析如何抓取评论数据。
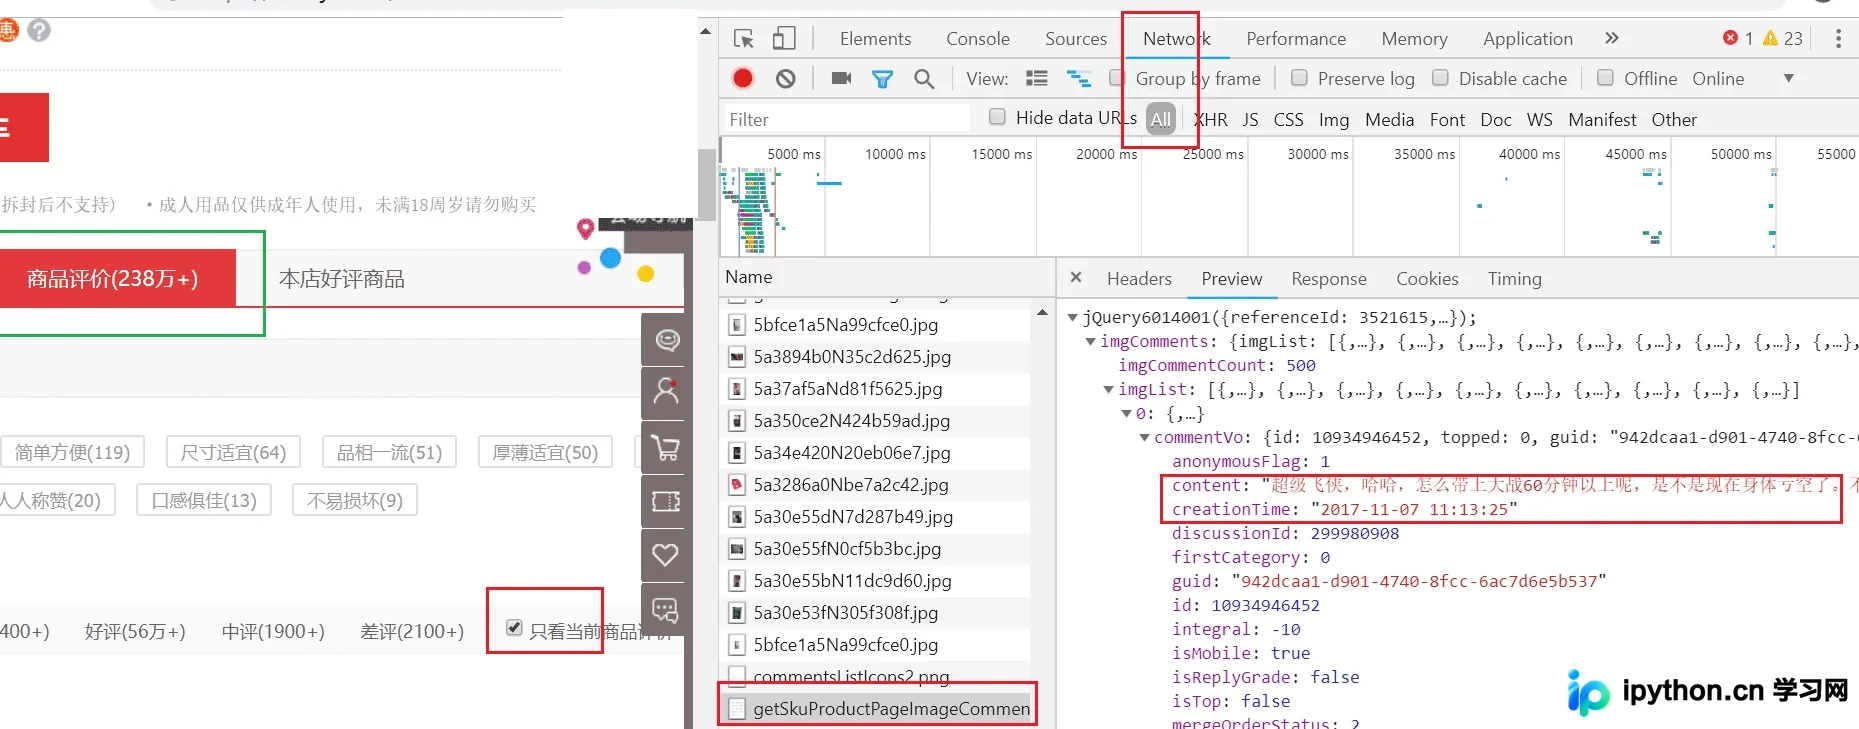
如上图所示,在开发者工具的Network(网络)选项卡中,可以观察到
https://club.jd.com/discussion/getSkuProductPageImageCommentList.action?productId=3521615&isShadowSku=0&callback=jQuery6014001&page=2&pageSize=10&_=1547042223100
这样的API链接,该链接返回JSON格式的数据。其中,productId参数对应TT产品页面中data-sku属性的值;page参数指定评论的页码。返回的JSON数据中,content字段代表评论内容,createTime字段代表下单时间。
具体实现代码如下:
def parse_product(page,html):
  doc = pq(html)
  li_list = doc('.gl-item').items()
  for li in li_list:
    product_id = li('.gl-i-wrap').attr('data-sku')
    brand_id = li('.gl-i-wrap').attr('brand_id')
    time.sleep(get_random_time())
    title = li('.p-name').find('em').text()
    price_items = li('.p-price').find('.J_price').find('i').items()
    price = 0
    for price_item in price_items:
      price = price_item.text()
      break
    total_comment_num = li('.p-commit').find('strong a').text()
    if total_comment_num.endswith("万+"):
      print('总评价数量:' + total_comment_num)
      total_comment_num = str(int(float(total_comment_num[0:len(total_comment_num) -2]) * 10000))
      print('转换后总评价数量:' + total_comment_num)
    elif total_comment_num.endswith("+"):
      total_comment_num = total_comment_num[0:len(total_comment_num) - 1]
    condom = {}
    condom["product_id"] = product_id
    condom["brand_id"] = brand_id
    condom["condom_name"] = title
    condom["total_comment_num"] = total_comment_num
    condom["price"] = price
    comment_url = 'https://club.jd.com/comment/skuProductPageComments.action?callback=fetchJSON_comment98vv117396&productId=%s&score=0&sortType=5&page=0&pageSize=10&isShadowSku=0&fold=1'
    comment_url = comment_url %(product_id)
    response = requests.get(comment_url,headers = headers)
    if response.text == '':
      for i in range(0,10):
        time.sleep(get_random_time())
        try:
          response = requests.get(comment_url, headers=headers)
        except requests.exceptions.ProxyError:
          time.sleep(get_random_time())
          response = requests.get(comment_url, headers=headers)
        if response.text:
          break
        else:
          continue
    text = response.text
    text = text[28:len(text) - 2]
    jsons = json.loads(text)
    productCommentSummary = jsons.get('productCommentSummary')
    # productCommentSummary = response.json().get('productCommentSummary')
    poor_count = productCommentSummary.get('poorCount')
    general_count = productCommentSummary.get('generalCount')
    good_count = productCommentSummary.get('goodCount')
    comment_count = productCommentSummary.get('commentCount')
    poor_rate = productCommentSummary.get('poorRate')
    good_rate = productCommentSummary.get('goodRate')
    general_rate = productCommentSummary.get('generalRate')
    default_good_count = productCommentSummary.get('defaultGoodCount')
    condom["poor_count"] = poor_count
    condom["general_count"] = general_count
    condom["good_count"] = good_count
    condom["comment_count"] = comment_count
    condom["poor_rate"] = poor_rate
    condom["good_rate"] = good_rate
    condom["general_rate"] = general_rate
    condom["default_good_count"] = default_good_count
    collection.insert(condom)
    comments = jsons.get('comments')
    if comments:
      for comment in comments:
        print('解析评论')
        condom_comment = {}
        reference_time = comment.get('referenceTime')
        content = comment.get('content')
        product_color = comment.get('productColor')
        user_client_show = comment.get('userClientShow')
        user_level_name = comment.get('userLevelName')
        is_mobile = comment.get('isMobile')
        creation_time = comment.get('creationTime')
        guid = comment.get("guid")
        condom_comment["reference_time"] = reference_time
        condom_comment["content"] = content
        condom_comment["product_color"] = product_color
        condom_comment["user_client_show"] = user_client_show
        condom_comment["user_level_name"] = user_level_name
        condom_comment["is_mobile"] = is_mobile
        condom_comment["creation_time"] = creation_time
        condom_comment["guid"] = guid
        collection_comment.insert(condom_comment)
    parse_comment(product_id)
def parse_comment(product_id):
  comment_url = 'https://club.jd.com/comment/skuProductPageComments.action?callback=fetchJSON_comment98vv117396&productId=%s&score=0&sortType=5&page=%d&pageSize=10&isShadowSku=0&fold=1'
  for i in range(1,200):
    time.sleep(get_random_time())
    time.sleep(get_random_time())
    print('抓取第' + str(i) + '页评论')
    url = comment_url%(product_id,i)
    response = requests.get(url, headers=headers,timeout=10)
    print(response.status_code)
    if response.text == '':
      for i in range(0,10):
        print('抓取不到数据')
        response = requests.get(comment_url, headers=headers)
        if response.text:
          break
        else:
          continue
    text = response.text
    print(text)
    text = text[28:len(text) - 2]
    print(text)
    jsons = json.loads(text)
    comments = jsons.get('comments')
    if comments:
      for comment in comments:
        print('解析评论')
        condom_comment = {}
        reference_time = comment.get('referenceTime')
        content = comment.get('content')
        product_color = comment.get('productColor')
        user_client_show = comment.get('userClientShow')
        user_level_name = comment.get('userLevelName')
        is_mobile = comment.get('isMobile')
        creation_time = comment.get('creationTime')
        guid = comment.get("guid")
        id = comment.get("id")
        condom_comment["reference_time"] = reference_time
        condom_comment["content"] = content
        condom_comment["product_color"] = product_color
        condom_comment["user_client_show"] = user_client_show
        condom_comment["user_level_name"] = user_level_name
        condom_comment["is_mobile"] = is_mobile
        condom_comment["creation_time"] = creation_time
        condom_comment["guid"] = guid
        condom_comment["id"] = id
        collection_comment.insert(condom_comment)
    else:
      break
如需获取完整的TT数据抓取及评论代码,请关注公众号“python_ai_bigdata”,并回复关键词“TT获取代码”。
品牌销量与产品特征分析
本次抓取共获取了8934条产品信息及17万条评论(购买)记录。
产品品牌分布分析
首先对8934个产品进行分析,以了解在京东平台上哪些品牌的TT销量最高。由于京东上销售的TT品牌多达299个,此处仅选取销量排名前10的品牌进行展示。
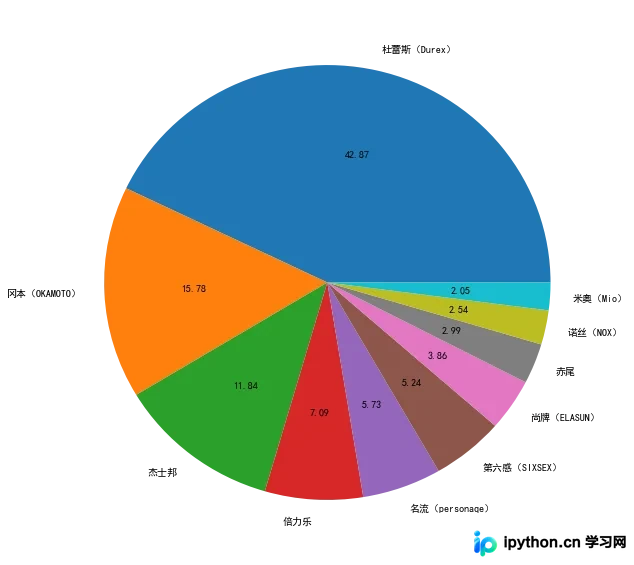
从上图结果可以看出,排名第一的是杜蕾斯,冈本位居第二,杰士邦排名第三。前10名品牌依次为杜蕾斯、冈本、杰士邦、倍力乐、名流、第六感、尚牌、赤尾、诺丝和米奥。在这10个品牌中,有5个品牌(倍力乐、名流、尚牌、赤尾、米奥)此前较少见,其余品牌较为知名,特别是杜蕾斯和杰士邦常年占据各大超市收银台的显眼位置。
这10个品牌的产地背景如下:杜蕾斯源自英国,冈本来自日本,杰士邦、第六感、赤尾、米奥和名流为国产(其中第六感是杰士邦旗下的避孕套品牌),倍力乐为中美合资,尚牌来自泰国,诺丝来自美国。
相关分析代码:
import pymongo
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
from pandas import DataFrame,Series
client = pymongo.MongoClient(host='localhost',port=27017)
db = client.condomdb
condom_new = db.condom_new
cursor = condom_new.find()
condom_df = pd.DataFrame(list(cursor))
brand_name_df = condom_df['brand_name'].to_frame()
brand_name_df['condom_num'] = 1
brand_name_group = brand_name_df.groupby('brand_name').sum()
brand_name_sort = brand_name_group.sort_values(by='condom_num', ascending=False)
brand_name_top10 = brand_name_sort.head(10)
# print(3 * np.random.rand(4))
index_list = []
labels = []
value_list = []
for index,row in brand_name_top10.iterrows():
  index_list.append(index)
  labels.append(index)
  value_list.append(int(row['condom_num']))
plt.rcParams['font.sans-serif']=['SimHei'] #用来正常显示中文标签
plt.rcParams['axes.unicode_minus']=False #用来正常显示负号

series_condom = pd.Series(value_list, index=index_list, name='')
series_condom.plot.pie(labels=labels,
         autopct='%.2f', fontsize=10, figsize=(10, 10))
销量最佳产品分析
可以通过产品的评价数量来间接判断产品的销售情况,通常评价数最多的产品也是销量最好的。
在评论数据中,有一个字段表示产品的总评论数。我们依据该字段进行排序,查看评论数量最多的前10个产品(即销量最高的产品)。
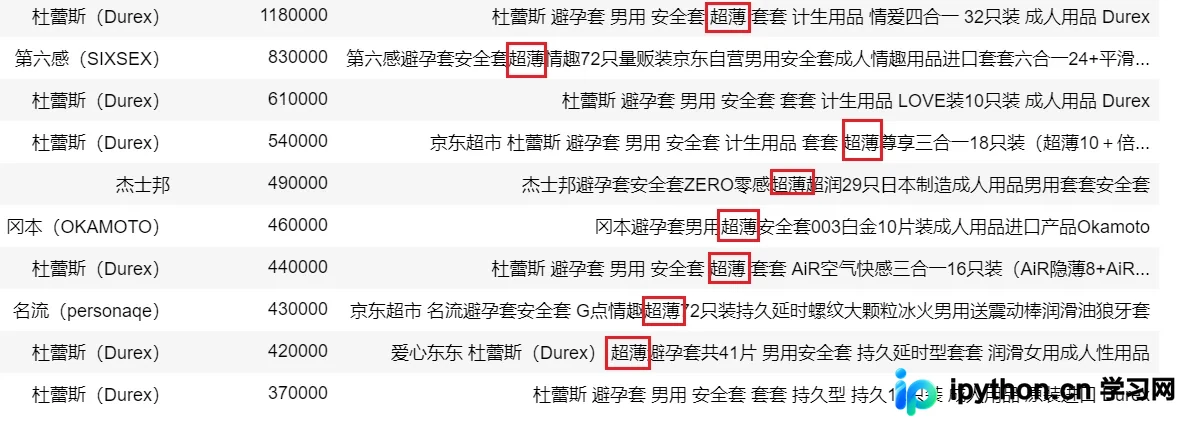
从上图可以看出,销量最好的依然是杜蕾斯的产品,前10名中占据了6席。其中,“杜蕾斯情爱四合一”以1180000万的销量排名首位。
最受欢迎的产品类型是超薄型TT,在前10名中占据了8席。持久型产品也颇受欢迎,而“狼牙套”竟然也上榜,这出乎意料。
销量趋势与渠道分布洞察
销量时间趋势分析
下图展示了TT销量最高的10天。
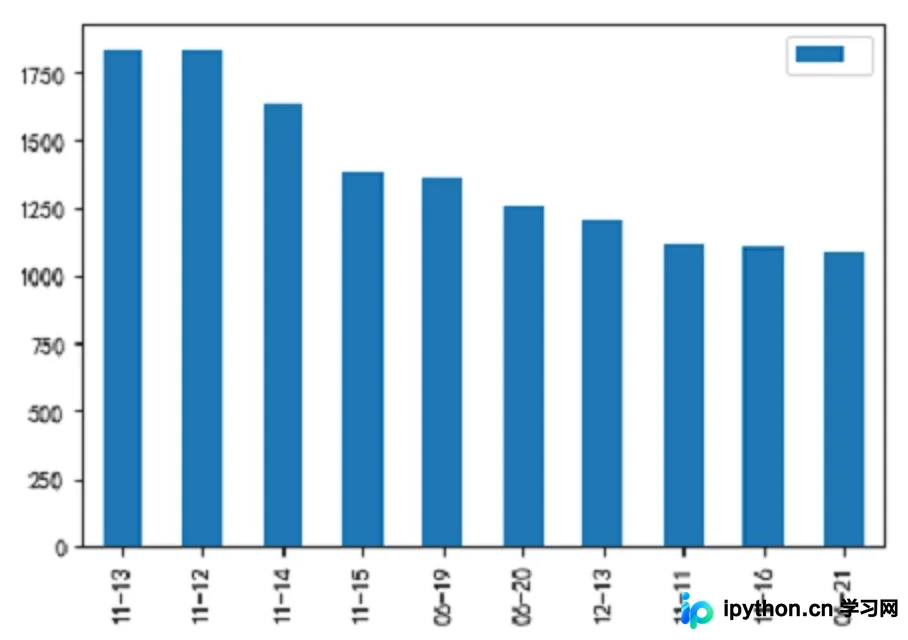
可以看出,这10天分别分布在6月、11月和12月,这与我们熟知的618、双11和双12购物节密切相关。
如今许多电商平台都设有自己的购物节,如618、双11和双12。由于单个产品最多只能显示100页评论,每页10条评论,因此单个产品最多只能抓取到1000条评论。对于销量高达118万的情爱四合一而言,1000条评论的代表性有限。但总体而言,通过上述分析可知,电商促销月份的销量通常较好。
下图展示了每月TT销售量的柱状图,进一步验证了上述观点。
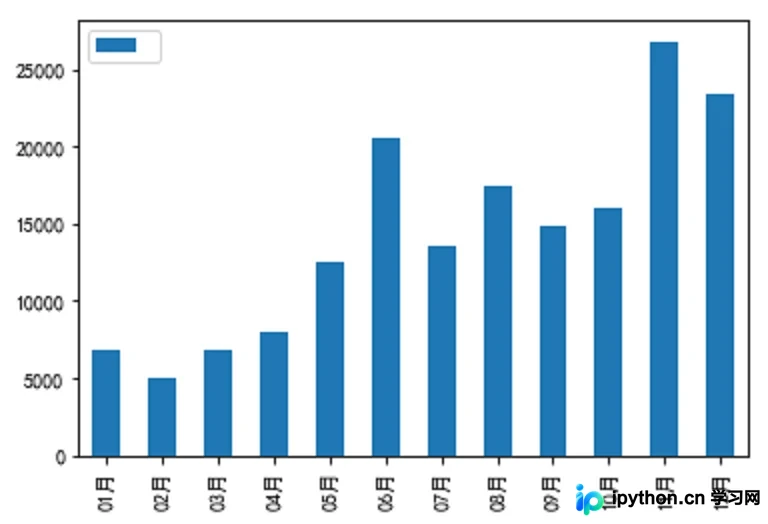
11月的销量最高,12月次之,6月份排名第三。
购物平台渠道分析
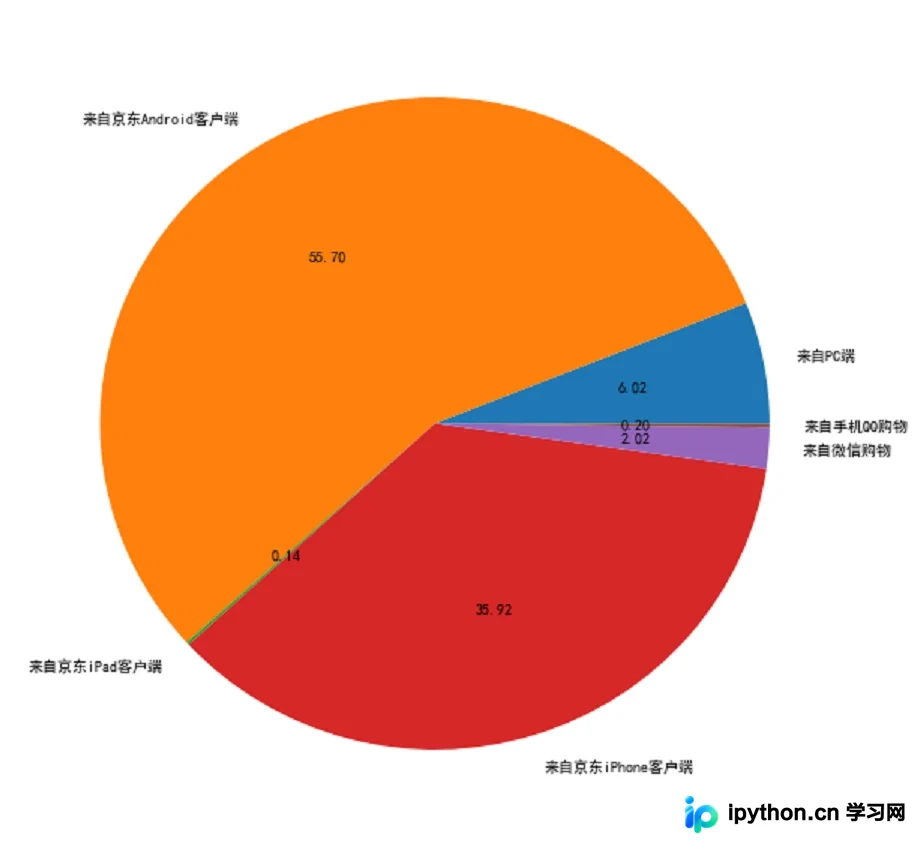
通过京东APP购买TT的用户最多,91%的用户来自京东Android客户端和iPhone客户端。6%的用户来自PC端,这与近年来4G网络的普及和发展有关。
通过上述分析可知,超薄型TT最受欢迎,杜蕾斯的产品销量最好,这与其营销策略密切相关。杜蕾斯的文案堪称教科书级别,每次发布都能引发广泛讨论,堪称经典。目前,移动端购买TT已成为主流,占据了90%以上的流量。
免责声明:本文内容仅供参考,不代表本站观点。转载或引用请注明出处。









