

Python 实现统计文本文件中单词频率的方法

发布时间:2026-10-13| 3人浏览过
本文介绍使用 Python 统计指定目录下所有文本文件中单词出现频率的方法。通过遍历当前路径下的 .txt 文件,利用 collections.Counter 进行词频统计并输出结果。
Python 统计文本单词频率实现
本文展示了一段使用 Python 统计文本文件中单词出现频率的完整代码示例,供读者参考。
#coding=utf-8
import os
from collections import Counter
sumsdata=[]
for fname in os.listdir(os.getcwd()):
  if os.path.isfile(fname) and fname.endswith('.txt'):
    with open(fname,'r') as fp:
      data=fp.readlines()
    sumsdata+=[line.strip().lower() for line in data]
cnt=Counter()
for word in sumsdata:
  cnt[word]+=1
cnt=dict(cnt)
for key,value in cnt.items():
  print(key+":"+str(value))
首先在与程序相同的目录下创建若干文本文件。例如创建两个文件,内容分别为 'hello python goodbye python' 和 'i like python'。运行上述程序后,将获得相应的统计结果。
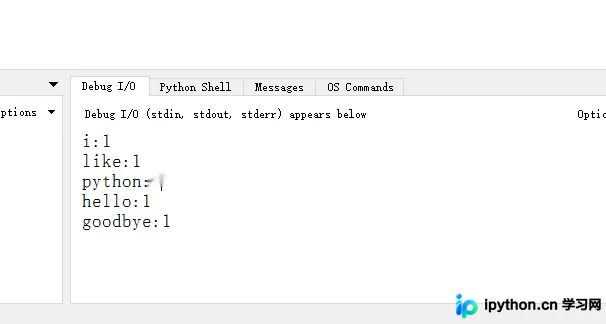
以上为 Python 统计文本中单词频率的详细介绍,希望能对大家有所帮助。如有任何疑问,欢迎留言,小编会及时回复。感谢大家对本站的支持!
免责声明:本文内容仅供参考,不代表本站观点。转载或引用请注明出处。









